Tracing Revolutionary Discourses

Leave a Comment
In our previous blog post in this series, Modeling Revolutionary Discourse, we outlined the integration of various analytic services and entry points to one of the collections -- the French Revolutionary Collection (FRC) -- we are using as part of ARTFL’s NEH funded Intertextual Bridges project.  This provided three distinct ways to approach the richness of the Newberry Library collection, through PhiloLogic4 search and analysis capabilities, through our new TopoLogic instance, and via a ranked relevance retrieval model.  We demonstrated the utility of different models of access and analysis and ways that combining these results could be used to pose different kinds of questions.  For example, using lists of topic words as the basis of rank relevance search can reveal unexpected relationships between documents and discourses.  

The Intertextual Bridges project is based on building ways to visualize and navigate relationships between disparate sets of collections.  For this project, we have started with seven different collections, representing a wide array of documentary materials concerning the French Revolution.  These include the Newberry FRC, the Archives Parlementaires (AP), the Baudouin Collection of Revolutionary Laws, the Journaux de Marat, as well as 18th century holdings from the ARTFL Frantext Collection, the Goldsmith-Kress Collection, and French holdings of ECCO.  The collections differ from each other in important ways and require specific search and retrieval schemes to allow for proper handling.  The individual speakers of the AP are searchable as part of particular sessions where as the Newberry does not have such data identified.  Simply doing a single build all of the collections into one database instance would reduce the analytic capabilities to the lowest common denominator.  Collection integration properly requires initial builds reflecting the specifics of each dataset, followed by abstraction to a top level interface.  


The first stage of database integration is development of a top level search and retrieval scheme.  For this preliminary work, each of the target collections we built as a separate PhiloLogic4 instance.  We then used the ARTFL Text Preprocessing Library, to extract metadata and word data from the standard representations generated by PhiloLogic4.  This allows us to use PhiloLogic4 services to support navigation back to the text.  The data extraction program allows the treatment of files as either entire documents or as collections of sub-units depending on the available data markup.  The FRC, for example, does not have internal subdivisions and it is treated as one text element per document.  By contrast, the Revolutionary Laws are tagged with divisions reflecting specific laws and other elements.  The Frantext selections and ECCO selections are typically divided into chapters.  Indexing and accessing text elements significantly improves search and retrieval tasks.  


For the purposes of our prototype, we are using the Python Whoosh indexing and search library. We expect to move to a more scalable ranked-relevance search engine for the final product. We have release an instance of our Whoosh-based search tool at:

     https://artflsrv03.uchicago.edu/mark/hub/multipledb.whoosh.html
The search form allows the user to input a list of terms to find and to limit results to the specific collections and/or to time periods.  Results are ordered by a standard relevancy calculation and we have appended a simple count of authors and titles at the bottom of the report. Note that we have turned links to the full text off at this time, since the underlying PhiloLogic4 instances are on an internal research machine which we expect to be updating in the future.  A full implementation will have full links to the documents and other functions, such as TopoLogic, as outlined in our previous blog post.  


For the query "grain subsistance recolte marche farine quantite pain denree prix bled" the search will return many results, displaying the first 100 (by default) instances, showing the relevance score of the document as well optional snippets as shown on the left.  
The snippets may be omitted from the report, which then generates a list of 

corresponding documents.  The search will retrieve and score subsections of documents, such as chapters or sessions in the same way as entire documents.  On the right one finds the continuation of the query for "grain subsistance...".  Limiting the query to the Revolutionary Laws collection will find specific laws on this subject, such as "Décret sur la police du commerce des grains l'approvisionnement des marchés des armées. Du 7 vendémiaire" of Year IV followed by (again in order of relevance to the query words) Décret qui fixe un maximum du prix des grains, farines et fourrages, et prononce des peines contre l'exportation. [11-9-1793].  

Rank relevance retrieval across multiple collections is a useful way to identify documents and passages of interest.  We are also finding that combining this type of query with word vectors representing Revolutionary topics to be a powerful tool to trace aspects of Revolution discourses to often unexpected sources.  We have included two topic models generated from the 26,000 documents Newberry French Revolution collection.  As described earlier, topic models are unsupervised techniques to identify topics in collections of documents.  Topic models identify the topic mix for every document in a collection and well lists of weighted words that are associated with each topic.  The TopoLogic instance of the 50 topic model can be found on
     https://artflsrv03.uchicago.edu/topic-modeling-browser/frc1787_99/


We have included the top ten words in each topic with a link to the ranked relevance search for that topic across all of the collections.  Clicking on Search will will query the words in this list against the Whoosh database.  The parameters are set to display the top 200 documents or sections from the entire collection.  We have also included the same data for a 100 topic model instance (click here).  No single topic model can properly capture the complexity of Revolutionary discourses.  Comparing the lists of 50 and 100 topics, you will find some are complementary, while others emerge only in the 100 topic model.  

While the static searches (clicking on Search with the set parameters) are useful, we recommend that you examine topics in more detail.  You can block copy the words from any of the topics to the search box and set the parameters as you see fit.  We have included on the search form one example.  This is a query for the words of Topic 4 (in the 50 topic model) "constitution pouvoir droit liberte nation peuple autorite homme principe propriete" in documents published before 1789, using the OR operator, and displaying the top 500 instances (click here to run this search).  This will return a list of documents or sections from pre-Revolutionary sources as shown on the right, led off by a translation of David Ramsay's History of the American Revolution and including the state constitution of Massachusetts. Scrolling down to the list of authors, one finds an interesting list of expected and rather unexpected authors including:


  • Du Buat, M. le comte (Louis-Gabriel), : 21
  • Mirabeau, Victor de Riquetti, marquis de, : 20
  • Holbach, Paul Henri Thiry, baron d', : 15
  • De Lolme, Jean Louis, : 14
  • Helvetius, : 13
  • Chamfort, Sébastien Roch Nicholas, : 11
  • Le Trosne, M. (Guillaume François), : 10
  • Mirabeau, Gabriel-Honoré de Riquetti, comte de, : 9
  • Le Mercier de La Rivière, Pierre-Paul, : 8
  • Bodin, Jean, : 8
  • Hume, David, : 7
  • Brissot de Warville, J.-P. (Jacques-Pierre), : 7
  • Franklin, Benjamin, : 6
  • Condorcet, Jean-Antoine-Nicolas de Caritat, Marquis de, : 6
Taking the words from Topic 43: "religion culte pretre eglise dieu fanatisme morale autel clerge divinite" and restricting the results to the 18th century holdings of ARTFL Frantext reveals the strong showing of Holbach (accounting for seven of the top ten most relevant sections) and Helvétius .  The top titles, recalling the sections are counted individually is also suggestive:


  • Lettres juives : 52
  • De l'homme : de ses facultés intellectuelles et de son éducation : 35
  • Essay sur l'hist. génèrale / Voltaire. : 25
  • Le christianisme dévoilé, ou, Examen des principes et des effets de la religion Chrétienne : 17
  • Dictionnaire philosophique : Comprenant les 118 articles parus sous ce titre du vivant de Voltaire, avec leurs suppléments parus dans les Questions sur l'Encyclopédie. : 15
  • Le comte de Valmont : 12
  • Système de la nature, ou, Des loix du monde physique du monde moral : 12
  • Voyage du jeune anacharsis : 11
  • Histoire critique de Jésus-Christ ou analyse raisonnée des Évangiles : 10
  • De la philosophie de la nature : 10
  • Les helviennes : 10
  • Les Incas, ou, La destruction de l'empire du Pérou : 10
  • La contagion sacrée ou Histoire naturelle de la superstition OU Tableau des effets que les opinions religieuses ont produits sur la terre. Tome I : 9
  • Le compère Mathieu : 8
  • Traité sur la tolérance : 8
Moving this time to the 100 topic model, we can look for traces of topic 80 "convention jugement mort royaute inviolabilite souverainete peine tyran crime depute" in pre-1789 texts. In essence, we are asking whether this topic on the tyrannical nature of the sovereignty of the king, so prevalent in revolutionary discourse, has any echoes in earlier texts. It is interesting to see in the results a mix of theoretical works (such as  Bodin's De la république, or Pufendorf's Droit de la nature et des gens), historical accounts (Raynal's Histoire du parlement d'Angleterre, or Boulainvillier's Etat de la France), or literary sources (Voltaire's Cromwell, or Mercier's L'an deux mille quatre cent quarante), thus providing researchers with a broad and diverse overview of discussions of this topic in the pre-revolutionary period. 

In highlighting the possibility of using word vectors that emerge from topic models of Revolutionary discourses, we might be guilty of teleological readings of these earlier texts.  This one approach is simply to demonstrate the the possibility of combining mixtures of algorithms to propose unexpected texts of potentially related interest.  As we move forward, we will be including topic models of the 18th century collections, to allow tracing of earlier topics into the Revolutionary era.  This is another level of navigation that we believe will help guide researchers through large collections, providing access to smaller segments of text are that more tightly focussed on specific issues and topics.  

-- The ARTFL Team


Read More

Modeling Revolutionary Discourse

Leave a Comment
Modeling Revolutionary Discourse

As part of our lead work on ARTFL’s NEH funded Intertextual Bridges project, we are pleased to release a prototype build of the Newberry Library’s French Revolution Collection (FRC), which integrates topic model browsing and search, relevancy searching, and full PhiloLogic4 services, in a set of interrelated functions. This post will describe the current state of this work, document some of the functionalities, and provide an outline of our next steps of development.

In 2017, the Newberry library released digital copies of more than 35,000 pamphlets totalling approximately 850,000 pages of it’s extremely rich holdings related to the French Revolution. Shortly thereafter, ARTFL project released versions of the Newberry FRC under PhiloLogic4 of this unparalleled resource. In a subsequent post, we described the collection, some of the capabilities of this initial installation and preliminary results using the tools deployed in this build.

We have two builds of the FRC under PhiloLogic. The first is simply a load of the entire collection of 38,377 documents as it was downloaded towards the end of 2017. We applied some error correction functions, which we recently modified slightly applied to the installation (search form). The bulk of our work has been aimed at the FRC collection for works from 1787-1799 with the aim to improve the data and metadata as well as remove duplicate documents. The 2017 release of the FRC at ARTFL contained 26,455 documents, where duplicates were identified by metadata comparison. Using data generated our new sequence alignment package TextPair, which identified both similar passages and possibly duplicated documents, we further reduced the collection to 25,935 documents. 

We currently have three entry points to collection. The basic component which underlies the whole system is PhiloLogic, our corpus query engine which houses the words index, the structure and the metadata of the collection:
          https://artflsrv03.uchicago.edu/philologic4/frc1787-99rev2b/
To facilitate the discovery of documents relevant to search queries, we added on a ranked-relevance engine, called Whoosh, which is built on top of the PhiloLogic index:
          https://artflsrv03.uchicago.edu/mark/frc/frc1787-99.whoosh.html
Finally, as an additional way of exploring the topics and discourses that run through the FRC, we built a topic-modeling browser called TopoLogic, which also leverages the PhiloLogic instance:
          https://artflsrv03.uchicago.edu/topic-modeling-browser/frc1787_99/.
While all three systems have specific capabilities and reporting features and function as discrete units, because they share a single data feed model (built from the PhiloLogic index), they are designed to be interoperable, and hence provide links across one another. It is our belief that there is no all-encompassing algorithmic approach to text analysis, and that topic-modeling provides one view that may be worth exploring, but no more so than other methods.

TopoLogic is the latest entry in our quest to build value-added services on top of the standard PhiloLogic index, and leverage topic-modeling techniques to offer an alternate way of exploring text collections. Topic-modeling, the algorithmic technique which we use for this new navigational tool, is an unsupervised machine learning approach designed to facilitate the exploration of large collections of texts where no topical information is provided. As such, this computational method can be a truly useful way of gaining a sense of the topical structure of a corpus -- i.e. to find out what's in there -- and how words are clustered together to form meaningful discourses.

TopoLogic builds upon the topics and semantic fields generated by the algorithm to provide a web-based navigation system which lets users explore topics and discourses across time, as well as word usage within different contexts. The interaction of the three different schemes allows the user to navigate between alternative ways of considering topics across the collection. The following slides are designed to give some idea of how users may navigate between topics, word searches and other capabilities provided by these different systems.


In our experience, there are a number of caveats to consider when using this algorithmic approach to text analysis. First, while topic-modeling is able to uncover relationships between words and documents without a training corpus (thus its unsupervised nature), it does require a certain number of priors, such as the number of topics to uncover, in order to function. In other words, the user of such method needs to determine (through trial and error) what that user deems to be the more meaningful representation of the corpus. Our experience has shown us that slight changes in the underlying texts (such as adding or removing a couple texts), or in the preprocessing steps (such as removing additional function words), can lead to drastically different results. All in all, we have always taken a very measured approach to our interpretation of topic models, and we strongly discourage against relying upon them as the sole source for text analysis.

The systems complement each other by providing checks on the results of particular functions. For example, in slide X above, we present the top 50 documents for topic 19 as measured by topic weight. In using a rank relevancy search for the top 10 tokens for topic 19, we arrive at a rather different list. The differences are due to the interaction of weighting schemes and relevancy measures. Both are useful approaches, but do, by design, deliver somewhat different results.

It is our pleasure to acknowledge that the Newberry Library has released this extraordinary resource under the Open Data Commons Attribution License, ODC-BY 1.0. We believe that this splendid collection and the Newberry’s release of all of the data will facilitate a generation of ground-breaking work in Revolutionary studies. If you find the collection useful, please do contact the Newberry Library to congratulate them on this wonderful initiative and how their efforts contribute to your research. Clovis & Mark
Read More

TextPAIR: a new high-performance sequence aligner

2 comments
We are happy to announce the release of TextPAIR, a new sequence aligner focused on detecting reuses in large body of texts. In many ways, TextPAIR is a successor to the old TextPAIR and PhiloLine released in 2009. But it also differs in important ways which we will highlight here.

The ARTFL-Project has long worked on intertextuality (see our papers section on the ARTFL site), and finding ways to detect similar passages in running text. Although we found great success with PhiloLine, particularly in the context of the Commonplace Cultures project, we also faced certain limitations which we wanted to address, particularly in the case of our recent project to explore the legacies of the Enlightenment in 19th century print culture.

Higher performance

The first issue that we wanted to address was that of performance. PhiloLine certainly wasn't slow, but it also wasn't designed to run a very large scale datasets, and remains to this day an experimental implementation meant to be replaced by a more optimized version. It served us well during the Commonplace Cultures project, where we ran the aligner against 200,000 texts. But the task also took 3 weeks to run, and needed to be broken up into several batches to run entirely. The results were certainly fruitful (over 40 million shared passages were detected!), but rerunning the task with a different set of parameters was out of the question given the deadline for the completion of the project.

As a result, when we started designing the new generation of our sequence aligner, we decided to focus on performance. We also wanted to leverage the rich Python ecosystem of NLP tools, so we decided that we would write this new package in Python (PhiloLine was written in Perl). After a redesign of the matching algorithm, the initial Python version was able to run about 1.5 to 2 times faster, but with also a much higher RAM usage, about 4-6 times more than PhiloLine. Certainly not a ground-breaking difference... Accelerating the alignment by parallelizing the task was out of the question given the memory cost of using multiprocessing in Python.

While we could have at that point decided to use Cython to gain C speed and parallelize the code, we decided to take a look at Go, a relatively new language developed at Google, which excels at running concurrent tasks, and runs significantly faster than Python. After a proof of concept rewrite in Go showed that we could run an alignment of all ARTFL-Frantext's 3,500 texts in under 4 hours on a single core, a task that took about 10 hours with the Python version,, we decided to go for a pure Go implementation of the core aligner code. While the RAM usage was a bit lower in Go than in Python, it was still somewhat high for our purposes, so we decided to use only 32 bit integers for all integer values (instead of the 64 bit default), effectively halving our memory usage. Our highest potential integer values are in the byte positions of passages within documents, and given that we are unlikely to find a 2,147,483,647 -- the maximum value for 32 bit signed integers -- byte text file anytime soon, there was no risk in switching to 32 bit integers. 

After a number of optimizations to the code, we were able to bring down the runtime of our ARTFL-Frantext alignment to a mere 11 minutes (!!!), leveraging all 16 cores (and 32 threads) of our server. With the Python preprocessing included (which combines various normalization steps and the ngram creation), as well as the database loading and web application building, it took a total of 20 minutes to go from the PhiloLogic parsed output to a full functioning web application capable of search through the 60,000 alignments. As a result of these optimizations, we were able to compete the alignment of our Enlightenment legacies project, which compared 1,300 texts from before the 19th century to 115,000 files from the TGB collection, in about 4 hours, most of which was spent preprocessing and filtering the OCR files from the TGB. We were able to run this alignment multiple times using different parameters in order to obtain the best set of results.

A revamped preprocessing stage

A big aspect of the aligner rewrite was our decision to rely as much as possible on the fledging Python ecosystem for all of our text preprocessing. There are many libraries available for preprocessing, but we decided to leverage Spacy, a well-documented and ever improving NLP library, for part-of-speech tagging and lemmatization. We do plan on using more of its features in the future.

We have also worked on building a virtual modernization pipeline for both English (relying on Martin's Mueller's work on TCP resources) and French (using the work Marine Riguet did on modernizing old forms in ARTFL-Frantext). This is an important feature to have when comparing texts from different periods. The typical example in French would be converting old forms of the imperfect ending in -ois/-oit/-oient to -ais/-ait/-aient. 

As we were working on this code, we realized it would be more useful to break-up this preprocessing step from the TextPAIR code so we could reuse it for other text analysis work. We've therefore created a separate library, called text-preprocessing, which is available on Github, and which we are constantly working to improve separately from the TextPAIR code.

A much improved Web Application

The original PhiloLine had a web application associated with it, and which could be used to search through alignments. But the feature set was restricted to searching shared passages using various metadata filtering options. Following in PhiloLogic4's footsteps, TextPAIR's Web interface has added faceted browsing to aggregate reuses in a way that gives a better overall perspective on the reuses present in the database. We also offer a Time Series view of shared passages to better understand how any given author/work has been reused accross time. And finally, we've worked on getting it integrated into PhiloLogic4 (when alignments were built from PhiloLogic4 output) by providing contextual links that take you straight to a PhiloLogic instance. 

Future work

We are looking to improve the current version of TextPAIR on different fronts:
  • Provide an alternate matching algorithm that can link together more loosely related passages
  • Allow for easier configuration of various components of the aligner and Web Application
  • Include a contextualization feature within TextPAIR (as an alternative to linking to a PhiloLogic instance)
  • Provide visualizations of alignments showing clusters of reuses, as well as of document to document shared passages

Some examples of currently running alignment databases


TextPAIR is fully open-source, and we gladly welcome any comments and/or contributions.


Read More

Evaluating the Practices and Legacy of the Enlightenment on 19th Century Print Culture

Leave a Comment
ARTFL is proud to announce the release of two large-scale sequence alignment databases built within the context of a collaborative project with l'Observatoire de la Vie Littéraire (OBVIL). The goal of this project was to investigate the legacy of the French Enlightenment on 19th century print culture. Thanks to the release by the BNF of the "Très Grand Bibliothèque" (TGB), a collection of 128,000 texts from their digital archive, we attempted to evaluate the presence of Enlightenment discourse within the French 19th century, relying on well-known text-reuse detection techniques. This project represented a natural outgrowth from previous research into sequence alignment in large collections, and resulted in the open-source release of TextPAIR, a high performance sequence aligner capable of comparing hundreds of thousands of documents in a mere 4 or 5 hours.

We used two well-curated datasets from the ARTFL Project holdings to form the test samples to identify Enlightenment discourse. The first are the 1,367 documents that comprise the pre-19th century holdings in ARTFL Frantext. This dataset contains a significant, though by no means complete, sample of major and minor French Enlightenment published works. We decide to retain Frantext’s 17th century holdings as part of this study. Thus, the most frequent authors with more than 10 works in this collection are shown in Table One (see bottom of post). The second sample is the complete text of the Encyclopédie of Diderot and d’Alembert as found in the ARTFL edition of this famous work. As mentioned, the ARTFL Frantext corpus and the Encyclopédie are both curated collections that have been largely corrected of input and other errors as well as being reasonable close transcriptions of the original documents with most later editorial interventions having been removed.

The TGB collection, which was meant to be a representative sample of French 19th century print culture, is comprised 128,441 documents which were digitized using Optical Character Recognition. As expected, the quality of the raw data varies widely depending on a whole range of factors, including age, preservation status and print quality, though it was overall of good quality. On the other hand, the document-level metadata was quite inconsistent, and sometimes incorrect, so our collaborators at the Observatoire de la Vie Littéraire had to perform some extensive preliminary work in order to get the data ready for our alignment experiments. This included a number of authorship attribution issues, as well as normalizing the spelling of each author found in the corpus. Additionally, while the vast majority of the texts in the TGB were published during the 19th century, the collection has a significant number of documents which were originally published before 1800. Most of these documents were reprints of earlier texts in complete or selected works or, less commonly, as individual reprints. We used a series of heuristics based on the metadata provided by the BNF to eliminate duplicates and texts originally published before 1800. We removed 17,063 documents from the TGB sample, with the top authors removed listed in Table Two (see bottom of post). This left 112,907 documents in the TGB sample. There are, of course, some titles that should have been retained in the sample and others that should have been removed, since the criteria for removal was based on fairly simple heuristics, such as removing most titles identified as complete works and looking at author year of birth or death, where available, as another criteria. Given that our goal was to draw a picture of the legacy of the Enlightenment using a representative sample of works published in the 19th century, this was a well worth tradeoff given the potential for many false positive reuses that would have been detected from leaving in texts originally written in previous centuries.

Since the primary task of this project is the identification of reused passages, we used the combined word lists of the Frantext sample and the Encyclopédie as the list of words to index in the TGB for both search and alignment applications. This was done in order to reduce the number of unique words (types) to a manageable level and to ignore all the potential OCR errors using the well attested word list of work from our well-curated texts. It did not have an impact on the alignment tasks since we use exact n-gram matching, so any words not found in the source text word list would not be found in the target text. We retained 193,908 types, amounting to a total of 2.1 billion words (tokens). 

TextPAIR (Pairwise Alignment of Intertextual Relations)
While the ARTFL Project had built text alignment packages in the past, this system was not built for very large-scale comparisons -- 100,000+ document ranges. As such, we wanted to create a new software package that could retain the strengths of PhiloLine while addressing the problem of scalability. Speed and scalability is important since data-mining projects often make progress through multiple runs testing various parameters and settings. Thus it was necessary for us to build a tool that we could rerun multiple times without having to wait for weeks for results to come in, as had been the case with the original implementation of PhiloLine.

The TextPAIR package was written over the course of many months during which the team at the ARTFL Project was in regular contact with the team at OBVIL in order to gather as much feedback as possible during the development phase. Its algorithm is based on the same principle used in PhiloLine, combining an n-gram representation of text with an alignment logic inspired by research in DNA sequencing. The alignment software comes with a web application designed to facilitate the exploration of the text-reuses found during the detection phase. This application includes both a faceted browser and a time series feature.

Detecting identical or similar passages requires a one-to-one document comparison of every text in the dataset. Our new program, called TextPAIR, generates a list of similar passages (based on a set of flexible matching parameters) shared between any two texts. This simple approach allows us to find borrowings and other instances of text reuse, from quotations to uncited passages and paraphrases, over large heterogeneous corpora. ln order for TextPAIR to find shared passages, we apply a number of transformations to the texts. For instance, we remove all stopwords, common function words, and short words which tend to be ubiquitous and, thus, are not reliable markers of textual similarity. We also reduce the number of orthographic variants by normalizing spelling where possible, and eliminate all words that occur only once in the dataset. The remaining words are then grouped into units of n-number of words – or n-grams – where each unit overlaps with the preceding and following group. These n-grams form a representation of the text that privileges word rareness over ubiquity, unlike textual representations that retain every single word.

Only once we have performed these textual transformations can we start comparing documents to one another. Because it is designed to run on many thousands of texts, TextPAIR’s matching algorithm is relatively simple and straightforward. Any more complex alignment algorithm, such as the Smith-Waterman algorithm, would significantly increase processing time. The basic principle of our text aligner is to compare sequences of n-grams between two documents. Whenever TextPAIR finds matching n-grams, a relatively rare occurrence, it continues comparing until it no longer finds sufficient matching n-grams. It then determines whether the number of contiguous matching n-grams is large enough to constitute a meaningful shared passage.

The TextPAIR package was built using cutting-edge technologies. Installed as a Python package, it includes a text preprocessing component written in Python, a sequence aligner written in Go to maximize speed and scalability, and a single-page web application written with the VueJS framework to guarantee maximum interactivity when text alignments are deployed in the browser. The package is available as open-source on Github, with accompanying documentation meant to assist other research groups in installing and running their own text-reuse experiments.


TextPAIR: General Results and Usage overview
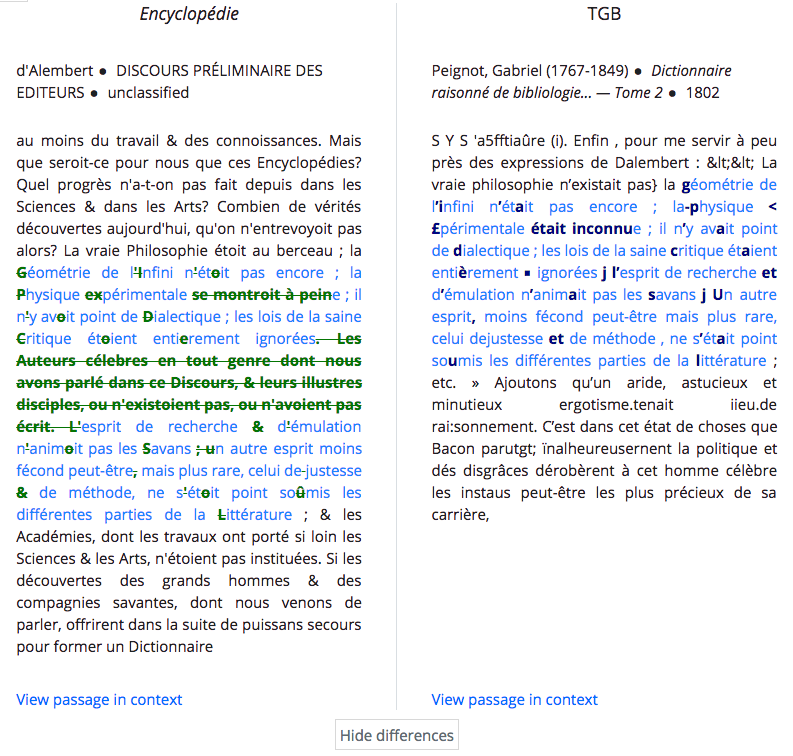
The sequence alignments of the pre 19th century sample of Frantext and the Encyclopédie against the 112,000 documents of the TGB produced a large number of resulting passage pairs, the basic unit of analysis. Figure One shows a typical alignment pair, in this case a passage from the famous Discours Préliminaire reused with some indication of the source in Peignot’s Dictionnaire raisonné de bibliologie. It is important to note that the TextPAIR can detect similar passages with considerable variations which can arise from textual insertions, deletions or modifications along with data capture errors, differences in spellings and word order changes. The figure below uses the “Show differences” feature to highlight the variations between the passage pair.


Each record of the result database stores metadata for each document of the pair from the TEI headers, byte locations and offsets in the corresponding text data files, the passages in question, the size of the alignments, and whether or not the alignment is considered banal. We have in other instances, put addition data describing the passage pair, including whether or not it was from the Bible and related to other passages in the set (commonplace tracking). The databases are loaded into a PostgreSQL relational database with a dedicated interface to allow users to query the document pairs, get summary results and navigate to the original documents at will.

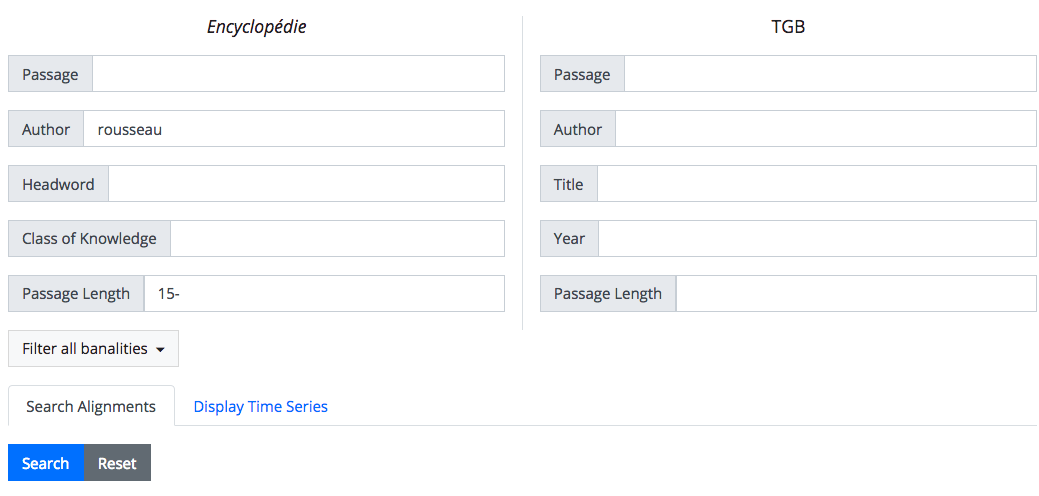
The alignment between the Encyclopédie and the TGB resulted in almost 117,000 records. This number is somewhat deceptive since it contains a number of banal alignments, such as the title of the Encyclopédie and other uninteresting similar passages. Similarly, the alignment between the pre-19th century of ARTFL Frantext and the TGB resulted in just under 295,000 passages, which is reduced to over 201,000 passages when removing short and banal passages. Such filtering is among the many features of the alignment result database implementation. The figure below shows the query form of the Encyclopédie to TGB alignment database, which supports metadata queries to allow the user to focus on specific questions, in this case a search for all aligned passages from articles written by Rousseau.


The query returns 611 passages, as shown in the figure below, where the first reused passage in this query is his article Accolade, which is found pretty much verbatim in a dictionary of music from 1825. 


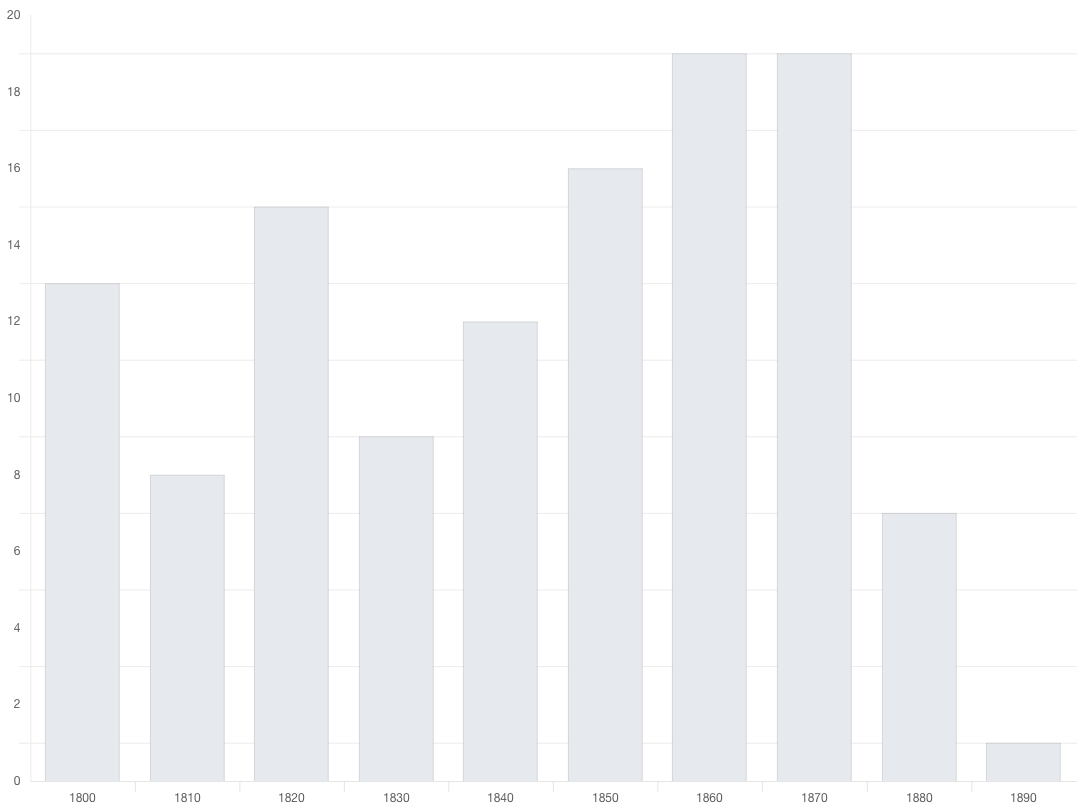
The query interface makes makes extensive use of facets, allowing the user to get frequencies broken down by different criteria. Breaking the reuses of Rousseau’s contributions to the Encyclopédie, it is interesting to note that while most of Rousseau’s entries in the Encyclopédie were about music, it is his political philosophy article “ECONOMIE” that is most reused in the 19th century. The interface supports the generation of time series graphs of the results. Figure Four shows that reuses of the article “ECONOMIE” was fairly consistent through the 19th century.


The Baron d’Holbach is another interesting case. As one of the philosophes with the most notorious reputation as a free-thinking materialists he contributed some of the most controversial articles to the Encyclopédie, such as “Représentants” or “Prêtres”. As shown in the figure on the left, it was his work on chemistry, mineralogy, and German history that is most reused in the 19th century. Instead of his scandalous article on “prêtres” being cited, you get the rather vanilla article “EVEQUE” which outlines the historical background of elector Bishops under the Holy Roman Empire. in fact, not one reuse of d’Holbach’s controversial material was found in the TGB, which sheds new light on our vision of Holbach as not simply an atheist propagandist, but as a man of science whose articles in various domains continued to be cited and used well into the 19th-century. This is an image of d’Holbach that rarely, if ever, occurs in modern intellectual and literary histories.

Algorithms and experiments
We believe that we can begin to use these techniques and these sorts of large-scale databases to refashion literary history, to give a more expansive vision of literary culture, etc.. by identifying various forms of intertextual activity, from reuse to referencing, in a broadened set of 18th-century corpora and to make use of various visualisation tools to navigate the output. In the context of this grant, we decided to concentrate on reuses of the Encyclopédie in the 19th century. While our interpretive work on this set of reuses is still in its initial phases, we have already been able to identify significant findings that change our understanding of the impact of the this great collective work on the 19th century.

We went into this project with the hypothesis that the engin de guerre of the Enlightenment had little to no impact in the 19th century. This was based on the general long-held general opinion on the subject, but it was also backed up by our initial experiments on the ARTFL Frantext corpus of works. However when we moved from this limited corpus to the large-scale TGB corpus, we moved from an exploration of what might be considered as a representative canon of “great works” of the 19th century to what in its vastness might be considered as something coming closer to a representation of a general cultural system.

This change in scale scale led us immediately to note the huge reuse of the Encyclopédie in the genre of dictionaries and encyclopedias published in the nineteenth century. In this area, the Encyclopédie was used as both a model and a source of information. But, more generally, the reuse of the Encyclopédie was more widespread across a broader range of publications than we had expected. So, from this point of view, in spite of the great developments in the sciences in the 19th century, the Encyclopédie remains an important source of information.

On the other hand, the articles that are most often cited in today’s discussions of the Encyclopédie, those heavily ideological articles laying out the aims and goals, those that make us see the Encyclopédie as an engin de guerre for the philosophes, are cited less often than we expected. Thus an author like d’Holbach is rarely reprised in the context of his specifically materialistic articles and more for articles he wrote on mineralogy and chemistry. All of this is to say, that Encyclopédie did have a significant impact in the 19th century, but it was not that which we had expected.

This work is just beginning and we will soon begin to look more closely at the bigger picture – not just the Encyclopédie in the TGB, but all of our various 18th century holdings (including the 18th century texts contained in the TGB corpus itself) – to broaden our understanding of reuse of 18th century in the post-Revolutionary era of the 19th century.


Direct Outcomes of this project
This project resulted in a number of related deliverables. Most importantly is the open source distribution of TextPAIR, as this provides a new model for handling very large scale alignment tasks.
https://github.com/ARTFL-Project/text-pair

The importance of this new software is underlined by the ARTFL Project release of a build of the Newberry French Revolution Collection which includes a open release of an alignment database of ARTFL pre-Revolutionary collection and the more than 26,000 Revolutionary documents. This allows scholar to look directly at the long standing question of the relationship between the Enlightenment and the Revolution.

The second and equally important deliverable from this collaborative work is the publication at ARTFL of both alignment databases as described above. These are complete installations of the alignment databases except that we have disabled links to the full texts of underlying datasets owing to agreements with various collaborators.

Home page of our alignment databases: http://artfl-project.uchicago.edu/legacy_eighteenth

ARTFL Encyclopédie to TGB alignment database: https://artflsrv03.uchicago.edu/text-align/encyc_vs_TGB_0803/

The ARTFL-Frantext to TGB alignment database: https://artflsrv03.uchicago.edu/text-align/frantext_vs_TGB_0803/

=====================================


TABLE One: Frequency of authors (shown with dates) in the Frantext Sample

Voltaire, 1694-1778.                                              85
Diderot, Denis, 1713-1784.                                        45
Corneille, Pierre, 1606-1684.                                     37
Molière, 1622-1673.                                               34
Aulnoy, Madame d'(Marie-Catherine), 1650 or 51-1705.              31
Fontenelle, M. de (Bernard Le Bovier), 1657-1757.                 23
Marivaux, Pierre Carlet de Chamblain de, 1688-1763.               22
Bossuet, Jacques Bénigne, 1627-1704.                              21
Saint-Simon, Louis de Rouvroy, duc de, 1675-1755                  20
Rousseau, Jean-Jacques, 1712-1778.                                17
Mersenne, Marin, 1588-1648.                                       16
Charrière, Isabelle de, 1740-1805.                                14
Fénelon, François de Salignac de La Mothe-, 1651-1715.            13
Montesquieu, Charles de Secondat, baron de, 1689-1755.            13
Prévost, abbé, 1697-1763.                                         13
Racine, Jean, 1639-1699.                                          13
La Fontaine, Jean de, 1621-1695.                                  11
Marot, Clément                                                    11
Balzac, Jean-Louis Guez, seigneur de, 1597-1654.                  10
Du Bellay, Joachim                                                10
Scudéry, M. de (Georges), 1601-1667.                              10


Table Two: Top Authors removed from TGB

Voltaire (1694-1778)                                             249
Molière (1622-1673)                                              243
Racine, Jean (1639-1699)                                         139
Corneille, Pierre (1606-1684)                                    132
La Fontaine, Jean de (1621-1695)                                 129
Chateaubriand, François-René de (1768-1848)                      112
Scott, Walter (1771-1832)                                        105
Boileau, Nicolas (1636-1711)                                     100
Fénelon, François de (1651-1715)                                  96
Scribe, Eugène (1791-1861)                                        84
Rousseau, Jean-Jacques (1712-1778)                                72
Rollin, Charles (1661-1741)                                       69
Diderot, Denis (1713-1784)                                        64
Louis (1755-1824)                                                 63
Florian, Jean-Pierre Claris de (1755-1794)                        60
Marmontel, Jean-François (1723-1799)                              58
Prévost, Antoine François (1697-1763)                             57
Sévigné, Marie de Rabutin-Chantal (1626-1696)                     56
Bachaumont, Louis Petit de (1690-1771)                            55
Cicéron (0106-0043 av. J.-C.)                                     55
Read More

PhiloLogic4: The Big Picture

Leave a Comment
While Clovis and I continue to document various aspects of PhiloLogic4's architecture and design, it may be helpful to keep in mind a sort of top-level "bird's-eye view" of the system as a whole.  PhiloLogic does a huge number of different things at different times, and it can be very difficult to keep them all organized. My best attempt to convey it in a single diagram is below:

As with PhiloLogic3, the foundation of all PhiloLogic services is a set of C functions, which are now collected together in a library called "libphilo", contained in the main PhiloLogic4 github repository.  These provide the high-performance compression, indexing, and search algorithms that distinguish PhiloLogic from most other XML and database technologies.  

This C library is the building block upon which all of PhiloLogic4's python library classes are built.  The two most important are 
  1. the Loader class, which controls parsing and indexing TEI XML files, and 
  2. the DB class, which governs all access to a PhiloLogic database.  

These classes themselves make use of other classes, most of which appear in the diagram above; it's extremely important to note that the Loader and the DB share almost no behaviors or components.  

This separation is a point of departure from most other database systems: in PhiloLogic4, the set of components that produce a database is distinct from the set of components that query an existing database.  We refer to the time when XML documents are ingested and indexed as load-time, and the time when a user queries the database as run-time or query-time.

Although one of the original design goals of PhiloLogic4 was to focus on the development of a more generalized library for TEI processing, it became clear at some point that a set of general behaviors was not enough, and that pragmatic development required two additional components:
  1. a general-purpose document-ingesting script, capable of handling errors and ambiguity, and
  2. a readymade web application suitable for most purposes, and customizable for others

These components were built as applications making use of the standard library components, and allow a PhiloLogic developer to specify all text- and language-specific features without modification of any shared functions.

The load_script has been described already in a previous post, but it is worth revisiting in this broader context.  The load script is responsible for three fundamental tasks:
  1. taking command-line arguments from the user, and passing all the supplied files into the loader class, along with additional parameters
  2. storing all system-specific configuration parameters: hostname, filesystem locations, etc.
  3. storing all text-specific configuration parameters: XPaths, tokenization regexes, special filters, etc.
When the load script has finished running, it moves the loaded database into an appropriate path in the web server's document tree, and creates a web application around it.  This is the very same web application described in Clovis's recent post.  It is created by copying a set of files stored elsewhere, typically in the PhiloLogic4 install directory, although specifying another set of files to "clone" from is possible.  It is important to note that, by convention, we refer to the web application together with the database that it accesses as a "database", as one almost never exists without the other, and this is reflected in the diagram above.  

The behavior of such a database/application is just as Clovis described it: all queries go to one of several "report generators", which interpret query parameters and access the database accordingly.  They produce a result object, a python object that maps very closely to a JSON object--that is, a single dictionary literal consisting of other literals, without functions, tuples, lambdas, objects, and other such structures that cannot be expressed in JSON.  This result object is then passed on to a Mako template file, which can transform the result into HTML viewable by a web browser, which is finally returned to the user--"finally" usually meaning under 100 milliseconds, of course.  

Over the coming months, Clovis and I will be describing many of these components in detail, and this post may be updated as this larger documentation project proceeds; but for now, I hope it serves as a helpful overview of PhiloLogic4.
Read More

General Overview of PhiloLogic4's Web Architecture

2 comments
Very early in the development of PhiloLogic4, we decided to separate the core library (the C core and Python bindings) from the actual Web interface. While there is still a clear separation between the Web environment and the library code, the two are nevertheless interdependent, which is to say that one cannot function independently of the other (unless you intend to use the library functions on the command line...)

As such, the Web component of PhiloLogic4 was designed as a Web Application, and each database functions as its own individual Web App. This allows for greater flexibility and customization. With PhiloLogic4, we wanted the Web layer to be the only part of the code a database developer has to deal with. We even went so far as to offer configuration options that drastically change the behavior of our various utilities. Before I start diving into each individual component (in later posts), I wanted to give a general picture of the Web app, as well as an idea of its features and flexibility.

The application is at its core a Python WSGI app which handles (most) requests through a dispatcher.py script that interprets queries and reroutes them to the relevant parts of the application. The results of requests are rendered in HTML thanks to the use of Mako, a powerful and easy-to-use template library. A description of the general layout of the Web App will give a better idea of how the PhiloLogic4 Web App functions.

There are four distinct sections (besides CSS and JS resources) inside the application:
  • The reports directory, which contains the major search reports which fetch data from the database by interfacing with the core library, and then return a specialized results report. These reports include concordance, KWIC (Key Word In Context), collocation, and time series. 
  • The functions directory, which contains all of the generic functions used by individual reports. These functions include parsing the query string, loading web configuration options, access control, etc. 
  • The scripts directory, which contains standalone CGI scripts that are called directly from Javascript code on the client side. These functions bypass the dispatcher and have a very specialized purpose, such as returning the total number of hits for any given query, or switching from a concordance display to a KWIC display.
The first three directories contain all that is necessary to return initial results to the client. The CGI scripts contained in /scripts provide additional functionality made possible by the use of Javascript in our Web Client. Significant work has been done to provide a dynamic and interactive Web interface, and this was made possible via heavy use of Javascript throughout the application, something which I'll describe in greater detail in another post.

Another design decision we made, somewhat late in the development process, was to rely on a CSS/JS framework for the layout of our HTML. We decided to use Bootstrap for its flexibility and responsiveness. As a result, PhiloLogic4 should work on any screen, be it phone, tablet or computer, although some functionality (such as KWIC reports) is hidden on smaller screens due to the limited space available.

Finally-- and I will go into much further detail in a separate post--we've designed a RESTful API that provides access to the full functionality of our web app. This is made possible by delaying for as long as possible the process of choosing to render search results as HTML or JSON. Basically, we expose the same results object to the HTML renderer (the Mako templates) that we do to any potential client. This design feature has allowed us to build a PhiloReader Android client application, focused on reading, by calling the relevant APIs needed for such functionality.

In my next post on the Web Application, I will go through the various configuration options available. 
Read More

PhiloLogic4 Load Script Architecture

Leave a Comment
Clovis and I have been doing a great deal of work lately on PhiloLogic4's document-loading process, and I feel that it's matured enough to start documenting in detail.  The best place to start is with the standard PhiloLogic4 load_script.py, which you can look at on github if you don't have one close at hand:

https://github.com/ARTFL-Project/PhiloLogic4/blob/master/scripts/load_script.py

The load script works more or less like the old philoload script, with some important differences:

  1. The load script is not installed system-wide--you generally want to keep it near your data, with any other scripts. 
  2. The load script has no global configuration file--all configuration is kept separate in each copy of the script that you create.
  3. The PhiloLogic4 Parser class is fully configurable from the load script--you can change any Xpaths you want, or even supply a replacement Parser class if you need to.
  4. The load script is designed to be short, and easy to understand and modify.
The most important pieces of information in any load script are the system setup variables at the top of the file.  These will give immediate errors if they aren't set up right.  


database_root is the filesystem path to the web-accessible directory where your PhiloLogic4 database will live, like /var/www/philologic/--so your webserver process will need read access to it, and you will need write access to create the database--and don't forget to keep the slash at the end of the directory, or you'll get errors.  

url_root is the HTTP URL that the database_root directory is accessible at: http://your.server.com/philologic/could be a reasonable mapping of the example above, but it will depend on your DNS setup, server configuration, and other hosting issues outside the scope of this document.

template_dir, which defaults to database_root + "/_system_dir/_install_dir/", is the directory containing all the scripts, reports, templates, and stylesheets that make up a PhiloLogic4 database application.  If you have customized behaviors or designs that you want reflected in all of the databases you build, you can keep those templates in a directory on their own where they won't get overwritten.  

(At the moment, you can't "clone" the templates from an existing database, because they actual database content can be very large, but we'd very much like to implement that feature in the future to allow for easy reloads.)

Most of the rest of the file is configuration for the Loader class, which does all of the real work, but the config is kept here, in the script, so you don't have to maintain custom classes for every database. 


For now, it's just important to know what options can be specified in the load script:
  1. default_object_level defines the type of object returned for the purpose of most navigation reports--for most database, this will be "doc", but you might want to use "div1" for dictionary or encyclopedia databases.
  2. navigable_objects is a list of the object types stored in the database and available for searching, reporting, and navigation--("doc","div1","div2","div3") is the default, but you might want to append "para" if you are parsing interesting metadata on paragraphs, like in drama.  Pages are handled separately, and don't need to be included here.
  3. filters and post_filters are lists of loader functions--their behavior and design will be documented separately, but they are basically lists of modular loader functions to be executed in order, and so shouldn't be modified carelessly.
  4. plain_text_obj is a very useful option that generates a flat text file representations of all objects of a given type, like "doc" or "div1", usually for data mining with Mallet or some other tool.
  5. extra_locals is a catch_all list of extra parameters to pass on to your database later, if you need to--think of it as a "swiss army knife" for passing data from the loader to the database at run-time.
The next section of the load script is setup for the XML Parser:


This is a bit complex, and will be explored in depth in a separate post, but the basic layout is this:
  1. xpaths is a list of 2-tuples that maps philologic object types to absolute XPaths--that is, XPaths evaluated where "." refers to the TEI document root element.  You can define multiple XPaths for the same type of object, but you will get much better and more consistent results if you do not.
  2. metadata_xpaths is a list of 3-tuples that map one or more XPaths to each metadata field defined on each object type.  These are evaluated relative to whatever XML element matched the XPath for the object type in question--so "." here refers to a doc, div1, or paragraph-level object somewhere in the xml.
  3. pseudo_empty_tags is a very obscure option for things that you want to treat as containers, even if they are encoded as self-closing tags.  
  4. suppress_tags is a list of tags in which you do not want to perform tokenization at all--that is, no words in them will be searchable via full-text search.  It does not prohibit extracting metadata from the content of those tags.
  5. word_regex and punct_regex are regular expression fragments that drive our tokenizer.  Each needs to consist of exactly one capturing subgroup so that our tokenizer can use them correctly. They are both fully unicode-aware--usually, the default \w class is fine for words, but in some cases you may need to add apostrophes and such to the word pattern.  Likewise, the punctuation regex pattern fully supports multi-byte utf-8 punctuation.  In both cases you should enter characters as unicode code points, not utf-8 byte strings.
The next section consists of just a few scary incantations that shouldn't be modified:


But the following 2 sections are where all the work gets done, and an important place to perform modifications.   First, we construct the Loader object, passing it all the configuration variables we have constructed so far:


Then we operate the Loader object step-by-step:


And that's it!  

Usually, these load functions should all be executed in the same order, but it is worth paying special attention to the load_metadata variable that is constructed right before l.parse_files is called.  This variable controls the entire parsing process, and is incredibly powerful.  Not only does it let you define any order in which to load your files, but you can also supply any document-level metadata you wish, and change the xpaths, load_filters, or parser class used per file, which can be very useful on complex or heterogeneous data sets.  However, this often requires either some source of stand-off metadata or pre-processing/parsing stage.  

For this purpose, we've added a powerful new Loader function called sort_by_metadata which integrates the functions of a PhiloLogic3 style metadata guesser and sorter, while still being modular enough to replaced entirely when necessary.  We'll describe it in more detail in a later post, but for now, you can look at the new artfl_load_script to get a sense of how to construct a more robust, fault-tolerant loader using this new function.

https://github.com/ARTFL-Project/PhiloLogic4/blob/master/scripts/artfl_load_script.py

Up next: the architecture of the PhiloLogic Loader class itself.
Read More

shlax and ElementTree

Leave a Comment
I've just pushed a few commits to the central philo4 repository;
mostly small bugfixes to the makefile and the parser, but I added a convenience method to the shlax XML parser.

As you may know, Python has a really nice XML library called ElementTree, but it has a few quirks:
1) it uses standard, "fussy" XML parsers that choke on the slightest flaw, and
2) it has a formally correct but incomprehensible approach to namespaces that is exceedingly impractical for day-to-day TEI hacking.

In this update, I've added a shlaxtree module to the philo4 distribution that hooks our fault-tolerant, namespace-agnostic XML parser up to ElementTree's XPath evaluator and serialization facilities. It generally prefers the 1.3 version of ElementTree, which is standard in python 2.7, but a simple install in 2.6 and 2.5.

Basically, the method philologic.shlaxtree.parse() will take in a file object, and return the root node of the xml document in the file, assuming it found one. You can use this to make a simple bibliographic extractor like so:


#!/usr/bin/env python
import philologic.shlaxtree as st
import sys
import codecs

for filename in sys.argv[1:]:
file = codecs.open(filename,"r","utf-8")
root = st.parse(file)
header = root.find("teiHeader")
print st.et.tostring(header)
print header.findtext(".//titleStmt/title")
print header.findtext(".//titleStmt/author")


Not bad for 10 lines, no? What's really cool is that you can modify trees, nodes, and fragments before writing them out, with neat recursive functions and what not. I've been using it for converting old SGML dictionaries to TEI--once you get the hang of it, it's much easier than regular expressions, and much easier to maintain and modify as well.
Read More
Next PostNewer Posts Previous PostOlder Posts Home